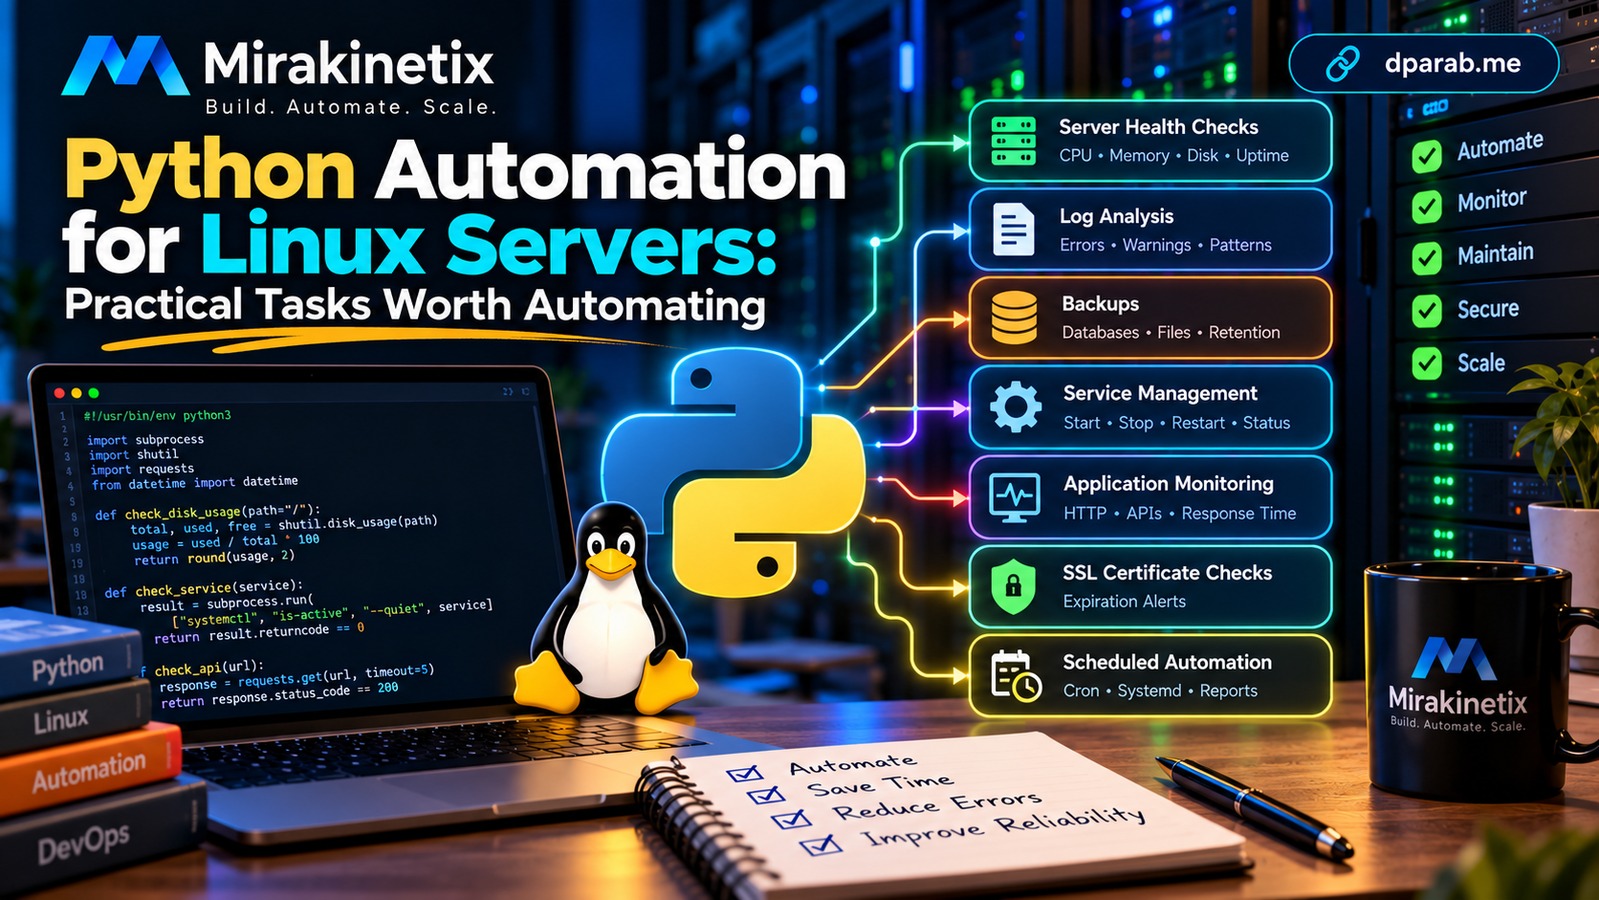
Linux administration often involves repetitive work: checking disk space, inspecting logs, restarting services, verifying backups, monitoring processes, and collecting system information.
These tasks may take only a few minutes individually, but repeating them across multiple servers can consume significant engineering time.
Python is particularly useful for this type of automation because it provides strong support for files, processes, networking, APIs, structured data, and system commands.
This guide is for Linux administrators, DevOps engineers, backend developers, SREs, and technical leads who want to automate practical server operations without turning simple tasks into unnecessarily complicated systems.
Start With Repetitive Tasks
Good candidates for automation usually have three characteristics:
They happen frequently.
They follow predictable steps.
Human involvement adds little value.
Examples include:
Checking disk usage
Searching application logs
Verifying services
Testing network connectivity
Checking SSL certificates
Creating backups
Cleaning temporary files
Collecting server information
Checking application health
Generating operational reports
The goal is not to automate everything.
Automate the work that is repetitive, measurable, and safe to execute automatically.
Check Disk Usage
A simple Python script can inspect filesystem usage:
import shutil

total, used, free = shutil.disk_usage("/")

usage = used / total * 100

print(f"Disk usage: {usage:.2f}%")

if usage > 90:
    print("CRITICAL: Disk usage is above 90%")
elif usage > 80:
    print("WARNING: Disk usage is above 80%")
else:
    print("OK")
This can become the foundation of a scheduled health check.
Instead of manually logging into every server, the script can run automatically and report only when attention is required.
Check Running Services
Linux services can also be checked programmatically.
For example, Python can invoke systemctl:
import subprocess

result = subprocess.run(
    ["systemctl", "is-active", "--quiet", "nginx"]
)

if result.returncode == 0:
    print("Nginx is running")
else:
    print("Nginx is not running")
This is useful for basic service monitoring.
However, automatically restarting a failed service should be treated carefully. A restart may hide the underlying problem rather than solve it.
A better workflow is often:
Detect → Log → Alert → Recover where appropriate → Investigate
Automate Log Analysis
Logs are another excellent automation target.
Suppose an application produces:
ERROR database connection failed
ERROR timeout connecting to Redis
WARNING queue latency increased
Python can scan logs and count important events:
from pathlib import Path

log_file = Path("/var/log/application.log")

errors = 0

with log_file.open(errors="ignore") as file:
    for line in file:
        if "ERROR" in line:
            errors += 1

print(f"Errors found: {errors}")
A production implementation could add:
Time-window filtering
Regular expressions
Structured JSON log parsing
Alert thresholds
Database storage
Email or webhook notifications
Automate Backups
Backup automation is another practical use case.
A script might:
Run a database dump.
Compress the output.
Add a timestamp.
Store it in a backup directory.
Verify the file exists.
Record success or failure.
Remove backups older than a defined retention period.
The important part is not simply creating a backup.
A backup that has never been tested is not a reliable recovery strategy.
Automation should eventually include restore verification.
Monitor HTTP APIs
Python can also perform application-level health checks.
import requests

response = requests.get(
    "https://example.com/health",
    timeout=5
)

if response.status_code == 200:
    print("Application healthy")
else:
    print(f"Application problem: {response.status_code}")
Always use timeouts.
Without a timeout, a network problem can cause the automation process itself to hang.
For production monitoring, also measure response time and validate the response content instead of checking only the HTTP status code.
Automate SSL Certificate Checks
Certificate expiration is another task that benefits from automation.
A scheduled Python job can:
Connect to a hostname
Read the certificate
Determine the expiration date
Calculate remaining days
Alert administrators before expiration
For example:
Certificate expires in 45 days → OK
Certificate expires in 14 days → WARNING
Certificate expires in 3 days  → CRITICAL
This is much better than discovering an expired certificate after users report that the application is unavailable.
Use APIs Instead of Manual Operations
Modern infrastructure often exposes APIs.
Python can integrate with:
Cloud platforms
Monitoring systems
Git repositories
Ticketing systems
Messaging platforms
Internal applications
A useful automation might be:
Server Alert
     ↓
Python Automation
     ↓
Collect Diagnostics
     ↓
Create Incident
     ↓
Notify Team
This turns monitoring into an operational workflow instead of simply generating alerts.
Scheduling Python Automation
Linux provides several ways to schedule scripts.
For simple tasks, cron is often sufficient:
*/5 * * * * /usr/bin/python3 /opt/scripts/check_disk.py
For more complex workloads, consider:
systemd timers
A task queue
A monitoring platform
CI/CD pipelines
Containerized workers
The scheduling mechanism should match the complexity of the task.
Make Scripts Safe
Automation can cause more damage than manual work if it is poorly designed.
A production script should consider:
Input validation
Timeouts
Error handling
Logging
Exit codes
Permissions
Locking
Retry limits
Configuration
Secrets management
Avoid scripts that silently fail.
For example:
try:
    perform_task()
except Exception as exc:
    logger.exception("Automation failed: %s", exc)
    raise
The exact error-handling strategy should depend on whether the task can safely retry.
Avoid Hardcoding Secrets
Do not put passwords, API keys, or tokens directly into Python source code.
Use:
Environment variables
Secret managers
Protected configuration
Appropriate file permissions
Also ensure secrets do not appear in logs.
Build Reusable Automation
A collection of unrelated scripts quickly becomes difficult to maintain.
Instead of creating:
disk.py
backup.py
api.py
logs.py
service.py
with duplicated logic, consider a reusable structure:
server-automation/
├── checks/
├── backups/
├── logs/
├── services/
├── notifications/
├── config/
└── main.py
Common functionality such as logging, configuration, notifications, and command execution should be reusable.
Concrete Python Automation Roadmap
A practical project can evolve in stages.
Phase 1 — Server Utilities
Build:
Disk checker
Memory checker
CPU checker
Process checker
Service checker
Deliverable: A command-line server health tool.
Phase 2 — Logging and Alerts
Add:
Structured logging
Thresholds
Exit codes
Email/webhook notifications
Configuration files
Deliverable: Automated health checks that notify when action is required.
Phase 3 — Scheduled Operations
Add:
Backup automation
Log cleanup
Certificate checks
API health checks
Use cron or systemd timers.
Deliverable: A practical Linux operations toolkit.
Phase 4 — Centralized Monitoring
Create a central API that receives results from multiple servers.
Linux Server
     ↓
Python Agent
     ↓
Monitoring API
     ↓
Database
     ↓
Dashboard
     ↓
Alerts
Deliverable: Central visibility across multiple servers.
Phase 5 — Production Hardening
Add:
Authentication
TLS
Agent identity
Rate limiting
Audit logging
Retry handling
Secure configuration
Monitoring of the automation itself
Deliverable: A maintainable production automation platform.
Common Mistakes
Automating without understanding the task: Automation can reproduce mistakes faster.
No timeout: Network operations can hang indefinitely.
No logging: Failed automation becomes difficult to diagnose.
Running with excessive privileges: Give scripts only the permissions they actually need.
No backup verification: Creating a backup does not prove it can be restored.
Unlimited retries: Failed automation can create additional load during an outage.
Hardcoded credentials: Secrets should never live in source code.
Final Thoughts
Python is an excellent tool for Linux automation because it sits between simple shell scripting and larger software systems.
Use shell commands where a simple command is enough. Use Python when the workflow requires structured logic, APIs, data processing, reusable components, or integration with multiple systems.
Start with one repetitive task.
Automate it safely.
Measure the result.
Then turn successful scripts into reusable operational tooling.
Build Linux Automation With Mirakinetix
If your team spends time repeatedly checking servers, processing logs, managing backups, monitoring applications, or performing manual operational tasks, Mirakinetix can help turn those processes into reliable automation.
From Python and Linux automation to APIs, monitoring platforms, databases, queues, and custom operational tools, the focus is on reducing repetitive work while keeping security, reliability, and maintainability at the center.
Have a repetitive server or business process that should be automated? Let's build it.
Mirakinetix — Build. Automate. Scale.


