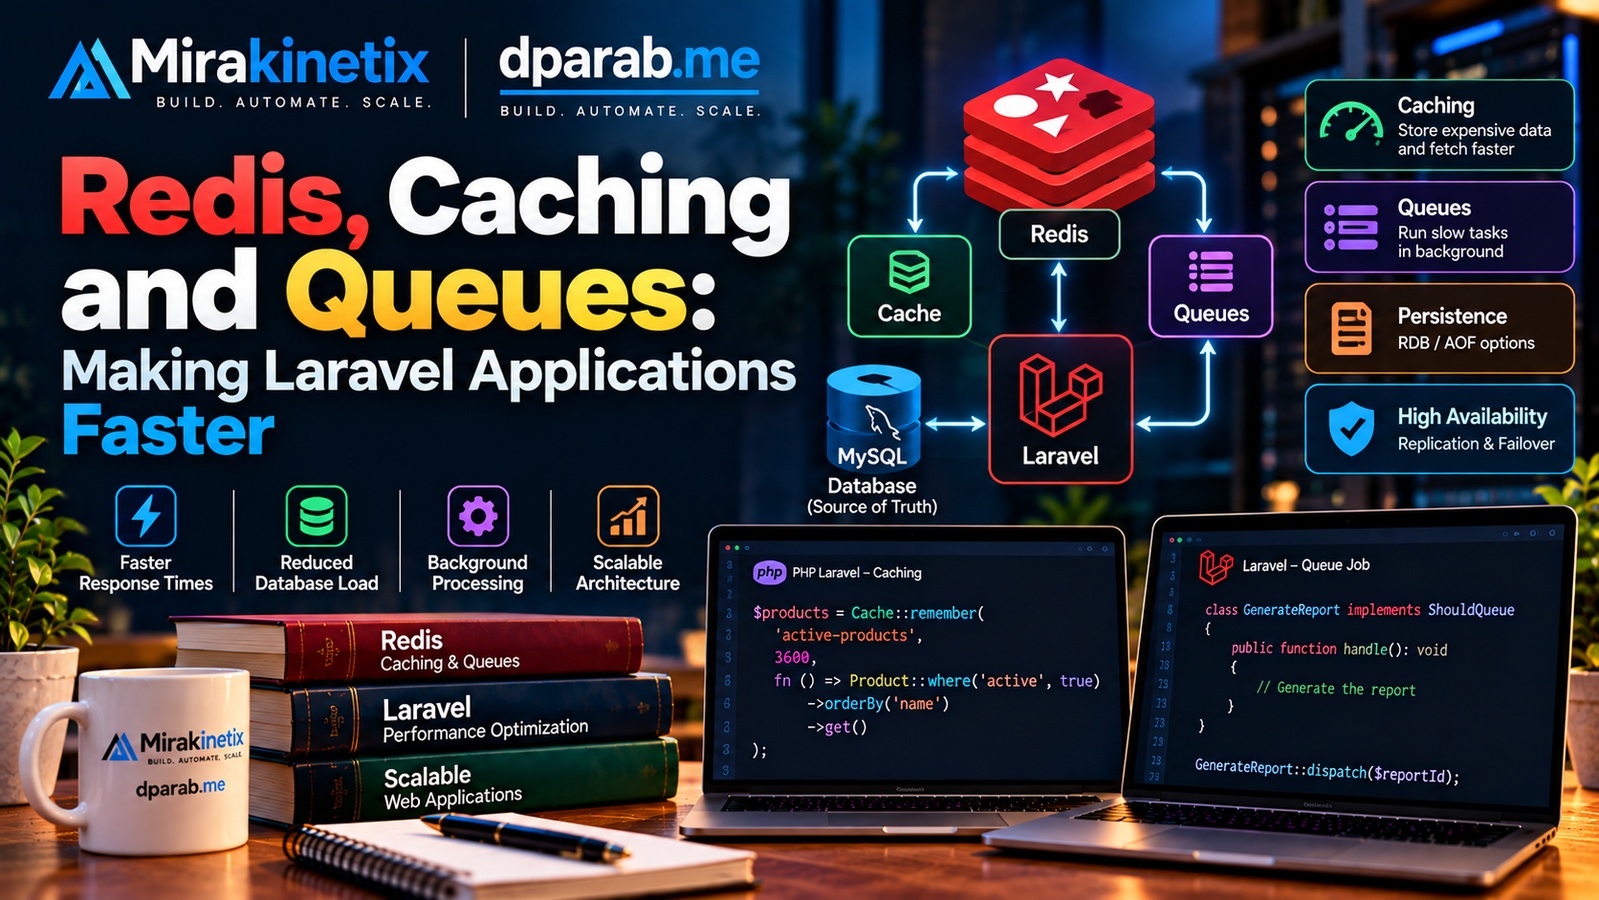
A Laravel application can start simple and still perform well. But as traffic, users, database records, and background workloads increase, performance problems eventually appear.
Pages become slower. Database queries increase. Reports take longer to generate. API requests wait for external services. Large jobs compete with normal web requests.
Three technologies can help address these problems:
Caching
Redis
Queues
They solve different problems, but together they can make Laravel applications faster, more responsive, and easier to scale.
What Is Caching?
Caching means temporarily storing data that is expensive to calculate or retrieve so it can be reused.
For example:
$products = Product::where('active', true)
    ->orderBy('name')
    ->get();
If this query runs on every request, the database repeatedly performs the same work.
Laravel can cache the result:
$products = Cache::remember(
    'active-products',
    3600,
    fn () => Product::where('active', true)
        ->orderBy('name')
        ->get()
);
The application can now reuse the cached result instead of querying the database every time.
Cache Expiration and Invalidation
Caching introduces the possibility of stale data.
For example:
Cache::remember(
    'product:' . $productId,
    now()->addMinutes(15),
    fn () => Product::findOrFail($productId)
);
When a product changes, the application may need to invalidate the old cache:
$product->update($data);

Cache::forget('product:' . $product->id);
A good caching strategy therefore considers both expiration and invalidation.
What Is Redis?
Redis is an in-memory data store commonly used for:
Application caching
Sessions
Queues
Counters
Rate limiting
Temporary application state
Distributed coordination
A common Laravel architecture is:
Laravel Application
        |
        +---- MySQL
        |
        +---- Redis
              |
              +---- Cache
              +---- Queue
              +---- Sessions
Redis is extremely fast because its primary working dataset is held in memory.
But there is an important misconception:
Redis is in-memory, but Redis does support persistence.
Redis Persistence and Failure Behavior
Redis can be configured with different persistence strategies.
No Persistence
For a disposable cache, Redis can run without persistence.
If Redis fails:
Application → Redis → FAILURE
                  ↓
              Cache lost
The application can rebuild the cache from MySQL.
This is often perfectly acceptable for cached data.
RDB Snapshots
RDB periodically saves snapshots of the Redis dataset to disk.
If Redis restarts, it can load the latest snapshot.
The trade-off is that changes made after the last snapshot may be lost.
AOF
AOF records Redis write operations so the dataset can be reconstructed after a restart.
Depending on the configured synchronization policy, there can still be some data loss after a sudden failure.
RDB + AOF
Redis can use both mechanisms, providing different recovery and durability characteristics.
The correct choice depends on how important the Redis data is and how much data loss the application can tolerate.
Persistence Is Not High Availability
This distinction is critical.
Persistence helps Redis recover data after a restart.
Replication and failover help Redis remain available when an instance fails.
For example:
                 Redis Primary
                      |
                 Replication
                      |
                      v
                  Replica
Redis replication is asynchronous by default. Therefore, a failure can result in recently acknowledged writes that had not yet reached the replica being lost.
So persistence, replication, and backups solve different problems.
For ordinary cache data, losing Redis may simply mean rebuilding the cache.
For important queue or application state, stronger reliability requirements may apply.
What Should Be Stored in Redis?
A useful rule is to ask whether the data can be rebuilt.
Usually safe to rebuild
Product caches
Dashboard statistics
API response caches
Temporary calculations
Needs more care
Sessions
Queue jobs
Counters
Rate-limit state
Temporary workflow state
Keep a durable source of truth
Critical business records such as:
Orders
Invoices
Financial transactions
Customer records
Audit records
should normally have durable storage such as MySQL.
A practical architecture is:
MySQL → Durable source of truth
Redis → Fast temporary data / cache
Queue → Background work
Redis can complement the database without replacing it.
What Are Queues?
Queues move slow work outside the user's HTTP request.
Consider a document upload that requires:
Storing the document
Scanning it
Extracting information
Generating thumbnails
Sending email
Updating search indexes
Instead of doing everything during the request:
User Request
     |
     v
Create Job
     |
     v
Return Response
     |
     v
Queue
     |
     v
Worker
The user gets a faster response while workers process the background tasks.
Laravel Queue Example
Create a job:
php artisan make:job GenerateReport
A simple job might contain:
class GenerateReport implements ShouldQueue
{
    public function handle(): void
    {
        // Generate the report
    }
}
Dispatch it:
GenerateReport::dispatch($reportId);
Redis can be used as the queue backend.
Multiple workers can process jobs concurrently:
Redis Queue
    |
    +---- Worker 1
    +---- Worker 2
    +---- Worker 3
    +---- Worker 4
Queue Failures Must Be Expected
Jobs can fail because of database problems, unavailable APIs, network failures, or third-party service errors.
Production queue systems should consider:
Retries
Retry delays
Failed jobs
Timeouts
Monitoring
Idempotency
For example:
public $tries = 3;
Retries also introduce an important problem: a job can run more than once.
A payment or order-processing job should therefore be idempotent so that retrying it does not accidentally create duplicate business transactions.
Cache vs Queue
TechnologyPrimary PurposeCacheAvoid repeating expensive workRedisFast in-memory data and workload coordinationQueueMove slow work outside the request
A simple way to remember it:
Cache makes repeated work cheaper.
Queues make slow work asynchronous.
Redis can provide infrastructure for both.
Practical Java Example
These concepts are not specific to Laravel.
A Java/Spring Boot application can use Redis for caching as well:
@Cacheable("products")
public List<Product> getActiveProducts() {
    return productRepository.findByActiveTrue();
}
Redis can be configured as the cache backend.
For background processing, Java applications can use Spring-based asynchronous processing or dedicated messaging systems such as RabbitMQ or Kafka, depending on the architecture.
The underlying principle remains the same:
Request
   |
   +---- Fast cached data
   |
   +---- Database
   |
   +---- Background processing
The framework changes, but the architectural problem is the same.
Do Not Cache Everything
Before caching something, ask:
Is it requested frequently?
Is the query expensive?
How often does the data change?
Can stale data be tolerated?
Can the data be rebuilt?
What happens if Redis becomes unavailable?
A database query taking 2 milliseconds may not need Redis.
Optimization should follow measurement.
Monitor Redis and Queues
Adding Redis does not automatically make an application faster.
Monitor:
Cache hit rate
Cache misses
Redis memory usage
Evictions
Persistence status
Replication status
Queue depth
Job processing time
Failed jobs
Worker utilization
If queue depth continually increases, the workers may not be keeping up.
If Redis memory continually approaches its limit, the caching strategy may need to change.
Practical Laravel Architecture
A production Laravel application might look like:
                         Internet
                            |
                     Load Balancer
                            |
             +--------------+--------------+
             |              |              |
        Laravel App    Laravel App    Laravel App
             |              |              |
             +--------------+--------------+
                            |
              +-------------+-------------+
              |                           |
            MySQL                       Redis
              |                     +-----+-----+
              |                     |           |
              |                   Cache       Queue
              |                                 |
              |                           +-----+-----+
              |                           |     |     |
              |                         Worker Worker Worker
The exact architecture depends on traffic, workload, availability requirements, and operational complexity.
You do not need a distributed architecture simply because Redis is available.
Common Mistakes
Caching everything without measuring performance.
Forgetting cache invalidation.
Using extremely long cache lifetimes.
Treating Redis as a replacement for MySQL.
Assuming Redis data always survives a restart.
Confusing persistence with replication.
Assuming replication guarantees zero data loss.
Running expensive work inside HTTP requests.
Ignoring failed jobs.
Creating non-idempotent jobs.
Running too few workers.
Adding infrastructure without identifying the actual bottleneck.
A Practical Optimization Workflow
Step 1: Identify slow requests.
Step 2: Identify expensive database queries.
Step 3: Determine which results are repeatedly requested.
Step 4: Cache appropriate data.
Step 5: Decide whether cached data can safely be rebuilt.
Step 6: Identify work that does not need to happen during the request.
Step 7: Move that work to queues.
Step 8: Design jobs for retries and idempotency.
Step 9: Use Redis where its characteristics make sense.
Step 10: Monitor caching, persistence, replication, and queues.
Step 11: Load-test the application.
Step 12: Scale based on actual workload.
Final Thoughts
Redis, caching, and queues are powerful tools, but they should not be added simply because they are popular.
Start with the bottleneck.
If repeated database queries consume resources, caching may help.
If requests wait for expensive processing, queues may help.
If fast temporary storage or workload coordination is required, Redis may be appropriate.
If Redis contains data that cannot simply be rebuilt, persistence and high availability must be designed deliberately.
Remember the distinction:
Persistence helps Redis recover data.
Replication helps Redis survive instance failures.
Backups help recover from larger failures or operational mistakes.
None of these automatically makes Redis a replacement for your primary relational database.
The best architecture is the one that solves the actual performance and reliability problem with the simplest architecture that can reliably handle the workload.


